Next.js 16 on Cloudflare Workers with OpenNext
 Nevil Krishna K9 min read
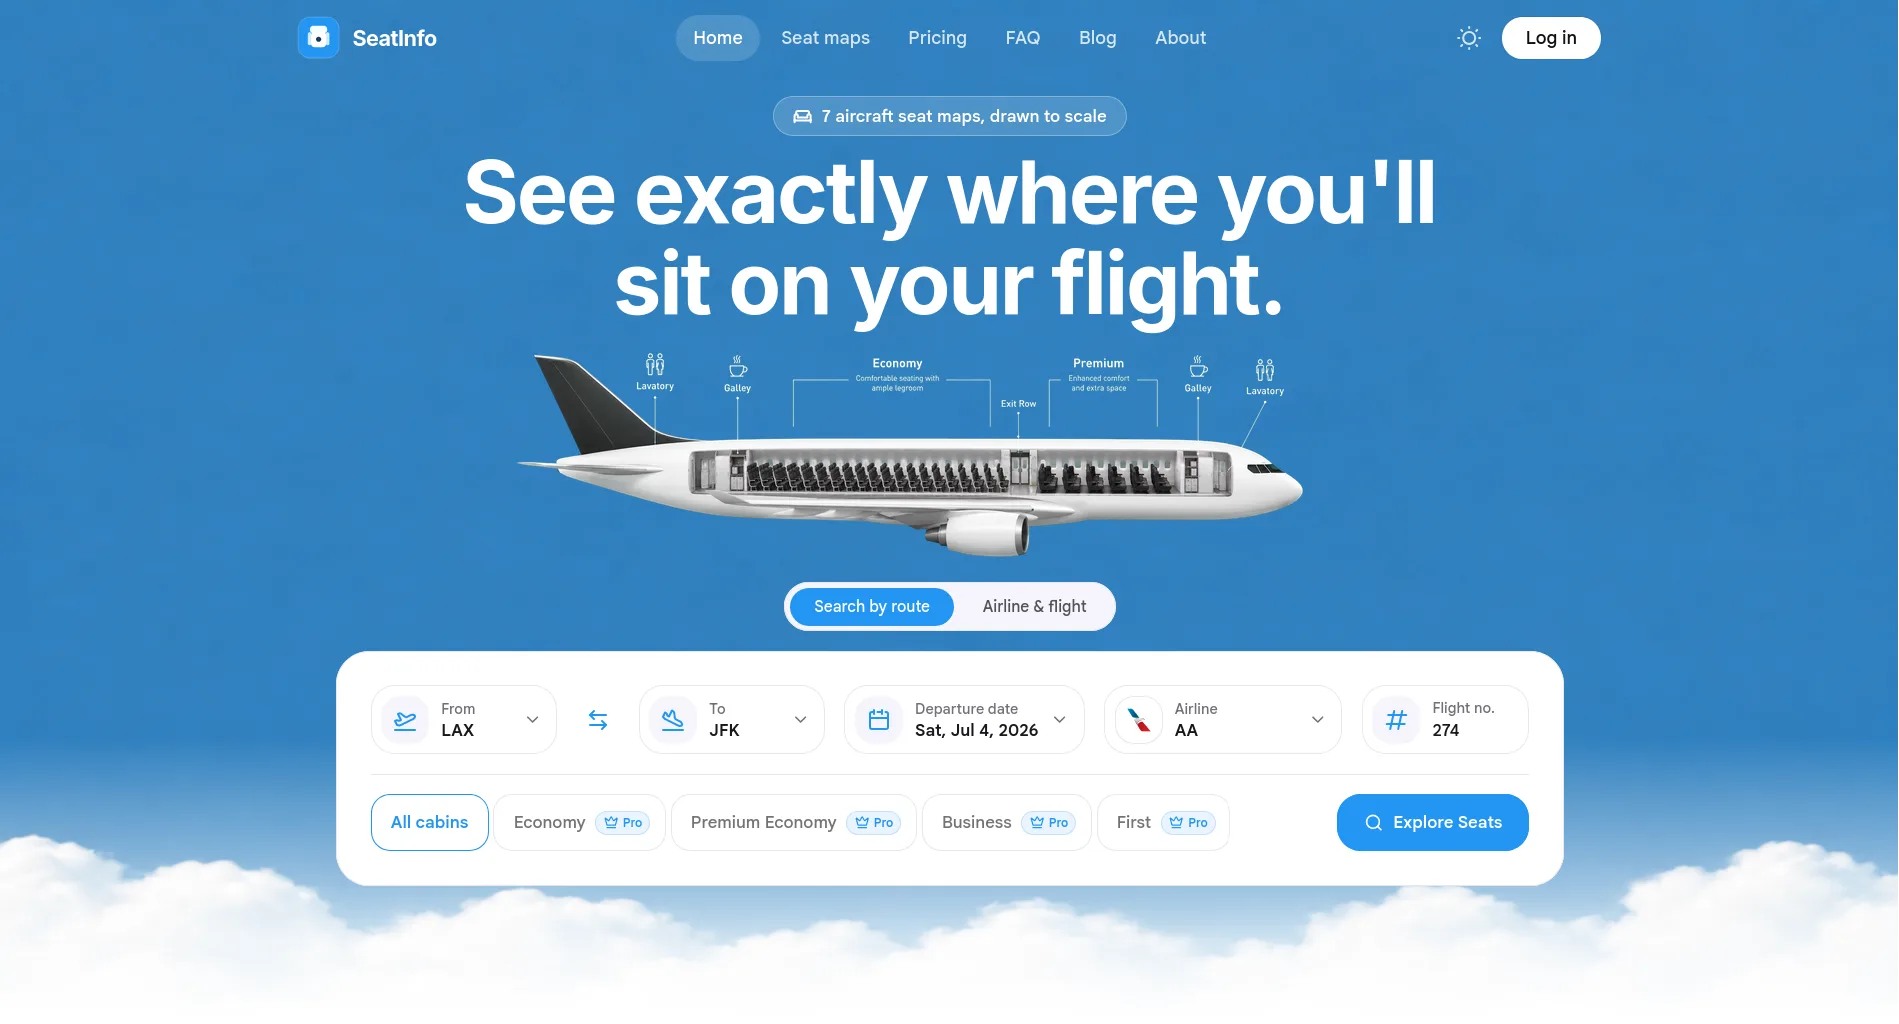
SeatInfo is a seat map product. You look up a flight and get a to-scale drawing of the cabin, every seat placed by its own coordinates and rotation, with zoom and pan and a catalog of aircraft and airlines around it. It runs on Cloudflare Workers, built with Next.js 16 and React 19, deployed through the OpenNext Cloudflare adapter and Wrangler.
I did the frontend and most of the platform work. This is what the stack was like, including what only showed up after a deploy.
Why Workers instead of Node
The choice was made for the read path. Catalog pages are read far more often than they change, a render is a cache lookup plus a small relational read, and Workers put both in the same location as the visitor with no container to keep warm. The price is a runtime that is not Node, and the ceiling you hit first is bundle size.
The compatibility flag for Node APIs plus a pinned compatibility date gets you most of the surface libraries expect. What it does not give you is a filesystem at runtime, long-lived in-process state, or native modules. Anything that reads a file on disk per request has to go through the static assets binding instead, and that is a change you discover after a deploy, because it works in the dev server.
The real constraint is that the whole Next.js server and every route end up in one Worker script, and Cloudflare limits that script to 3 MiB gzipped on the free plan and 10 MiB on paid. We went past 3 MiB, which made the paid plan a requirement rather than a preference. So the build got a size gate: it runs a dry-run deploy, reads the gzipped figure out of the output and fails over the limit. Measuring the output folder instead will lie to you.
Tree-shaking barrel imports keeps that number down: one icon library was pulling roughly 1,600 icons through about 170 import sites before it was configured.
What OpenNext actually does to a Next.js build
OpenNext takes the output of next build and repackages it as one Workers entrypoint plus a directory of static assets, then swaps out the three pieces of Next infrastructure that assume a Node server: the incremental cache, the tag cache and the revalidation queue. You pick an implementation for each in a config file. Your application code does not change, your deploy pipeline changes completely.
We put the incremental cache in R2, the tag cache in D1 so on-demand revalidation works, and the queue in a Durable Object. That queue is not optional in practice: the default is a stub that throws, so anything using ISR returns a 500 until you choose one.
import { defineCloudflareConfig } from "@opennextjs/cloudflare";
import r2IncrementalCache from "@opennextjs/cloudflare/overrides/incremental-cache/r2-incremental-cache";
import { withRegionalCache } from "@opennextjs/cloudflare/overrides/incremental-cache/regional-cache";
import doQueue from "@opennextjs/cloudflare/overrides/queue/do-queue";
import d1NextTagCache from "@opennextjs/cloudflare/overrides/tag-cache/d1-next-tag-cache";

export default defineCloudflareConfig({
  incrementalCache: withRegionalCache(r2IncrementalCache, {
    mode: "long-lived",
    shouldLazilyUpdateOnCacheHit: true,
  }),
  tagCache: d1NextTagCache,
  queue: doQueue,
  enableCacheInterception: false,
});
The regional wrapper is the line I would not skip. An object storage bucket lives in one region, so a bare incremental cache turns every cached page view into a cross-region read: around 400 ms warm and whole seconds on a cold isolate, which made the cached pages slower than the uncached ones. The wrapper keeps a copy in the local cache and refreshes it in the background.
The surprise was the build itself. next build runs with no Cloudflare bindings, so any page prerendered at build time that reads the database renders empty, and the adapter ships that render as the page's first cache entry. For a few minutes after every deploy, real pages served with their main content missing. The fix was a step between build and deploy that deletes those prerendered entries, so the first request renders on the Worker with real bindings.
Where D1 fits, and where it does not
D1 holds what a page render needs: the catalog, one row per published version of a map, and the tag index that on-demand revalidation reads. It does not hold anything live, write-heavy or transactional across services. The rule we settled on: if a render needs it and it changes a few times a day it belongs in D1, otherwise it stays behind the main API.
That split made publishing cheap. Every import writes a new version row and publishing moves a pointer, so going live is a row update plus a revalidation call, not a redeploy.
The import side is a pipeline. Each dataset is validated against a schema, then cross-checked for what a schema cannot express: that the identifier matches its folder, that the referenced image exists, that the per-cabin seat counts add up to the declared total. That runs as part of the build, so a malformed map fails the build instead of shipping a broken page. Only then does the pipeline emit the seed SQL and an upload manifest, push the images to R2 and apply the SQL. Images are addressed by version and served immutable, so a new version is a new URL and nothing needs purging.
Where D1 is wrong is a hot write path: reads are cheap, every write goes through one primary, and a heavily polled queue table will need rethinking.
Durable Objects and cron: the two things that made it feel like a backend
Neither is much code, and both close a gap a stateless Worker cannot. The Durable Object is the one the adapter ships for the revalidation queue: it gives the queue a single home, so a stale page is regenerated once rather than once per request that noticed. Cron gave us a scheduled handler, which meant background work without a second service.
Cron is the one place you leave the generated worker behind. It exports a fetch handler, so you write a thin entrypoint that imports it, adds a scheduled handler, and re-exports the queue class so the Durable Object migration still resolves.
{
  "main": "custom-worker.js",
  "triggers": { "crons": ["*/5 * * * *"] }
}
import handler from "./.open-next/worker.js";
import { runScheduledJobs } from "./jobs/scheduled";

export default {
  fetch: handler.fetch,
  async scheduled(controller, env, ctx) {
    ctx.waitUntil(runScheduledJobs(env));
  },
};

export { DOQueueHandler } from "./.open-next/worker.js";
Our scheduled run drains a translation job queue: recover rows abandoned by an earlier run, claim a bounded batch, do the work, write the result to object storage, mark the row finished. Two rules make it safe: every status transition is guarded on the current status, so overlapping ticks cannot both claim a job, and the batch size is a constant, because a cron invocation has its own CPU budget.
next-intl on the edge
next-intl works on Workers without ceremony, and the cost is a middleware in front of every request. Locale matching, retired-locale redirects and moved URLs happen in one pass there, because each extra pass is a real redirect the visitor pays for. The setting I would call load-bearing is turning off the library's automatic alternate links.
By default next-intl emits a Link header with an alternate per locale, built from the incoming request, so an http request advertises http alternates and the header set never quite matches the tags in your HTML. With it off, hreflang comes from two places, the document head and the sitemap, both absolute and both derived from one configured domain.
The second thing worth copying is keeping the served locale list in one exported array. The repository carries 33 message files, and the routes, the hreflang alternates, the sitemap alternates, the language picker and the translation queue all read from one constant. We serve English only at the moment, and turning the rest back on is one line. Locales that were served and then retired redirect to the English path with a 308 instead of 404ing a whole language tree, because those URLs are still in the index.
The deployed Worker has no public folder, so message files come through the assets binding with a long cache while the dev server reads them from disk.
The SEO baseline that came free, and the part that did not
Metadata, canonicals, structured data and sitemap routes are ordinary Next.js work and behave identically on Workers. What did not come free was status codes on cached pages. With the adapter's cache interception enabled, a cached notFound() render replayed as a 200 carrying the 404 body, a soft 404 on every hub page that had no content yet.
The interceptor answers a cache hit before the Next server runs and rebuilds the status from cache metadata that a not-found render does not carry. With it off, the request goes through the Next server, which serves the same cache entry and keeps the status, for a measured 3 to 9 ms per cached page.
Two Next.js behaviours mattered more than anything we added to the head. A dynamic route needs generateStaticParams to be cached at all, even if it returns an empty array; without it the route is left out of the prerender manifest and re-renders per request whatever the revalidate value says. And awaiting search params forces per-request rendering and disables prefetching for every link to that page, which is how four of our most important pages became the slowest ones.
Analytics sat next to this work: one module owns the Mixpanel client, every event name lives in one file, and the SDK is imported when the browser goes idle rather than at mount.
What I would tell someone starting this today
Set up the size gate and the local Workers preview on day one. Every problem that cost me real time here was invisible in the dev server, and all of it showed up the first time I ran the built Worker through Wrangler.
- Put a bundle-size check in CI before you have a size problem, measured from a dry-run deploy, not a folder listing.
- Assume the build has no bindings, and decide what each page renders when the database is unreachable.
- Choose your incremental cache, tag cache and queue before the first deploy; the default queue throws.
- Verify anything cache-shaped, including status codes, against the built Worker. The dev server has no cache layer to be wrong about.
- Keep one source of truth for locales and one for public URLs, and generate the rest from them.
Would I choose it again? For a read-heavy, content-shaped product, yes. If it were write-heavy or needed a long-running process, I would keep the same frontend and put that work elsewhere.
- Next.js
- Cloudflare
- OpenNext
- TypeScript
- SEO
Building something like this?
Tell me what you are building. You get a fixed scope and a fixed figure back, from the person who writes the code.